Remove Duplicate Lines
Clean up your lists by removing all duplicate entries.
About Remove Duplicate Lines
Effortlessly clean your datasets by removing duplicate lines. This tool is invaluable for developers, data analysts, and marketers who need to unique-ify large lists of emails, IDs, or logs quickly and securely.
How to Use
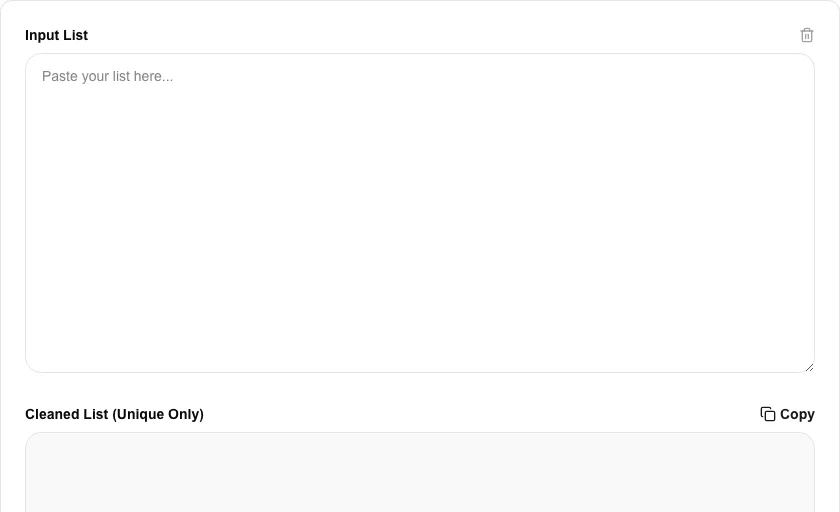
- Paste your list into the input box.
- The tool automatically identifies and subtracts redundant entries.
- Review the statistics comparing original vs unique line counts.
- Copy the cleaned, unique list for use in your spreadsheets or code.
Common Use Cases
- Cleaning up mailing lists to remove duplicate email addresses.
- De-duplicating log files or database export results.
- Stripping duplicate keywords from SEO research lists.
Technical Details
Implements efficient set-based logic to filter duplicates in O(n) time. All data remains in your browser, never touching a server.
Frequently Asked Questions
- Is it case-sensitive?
- The tool performs an exact string match for each line, so it is case-sensitive by default.
- Does it preserve the order?
- Yes, it keeps the first occurrence of each line and maintains the original order of the remaining unique items.
- Does the order of lines change after deduplication?
- By default, the original order is preserved — the first occurrence of each line is kept and subsequent duplicates are removed. An option to sort lines alphabetically after deduplication is also available.
- Can I do case-insensitive duplicate removal?
- Yes. Enable the case-insensitive option to treat 'Apple', 'apple', and 'APPLE' as the same line. Only the first-encountered casing is kept in the output.
- How do I remove near-duplicate lines with extra spaces?
- Enable the 'trim whitespace' option to strip leading and trailing spaces from each line before comparison. This catches duplicates that differ only in surrounding whitespace, which is common when copying from spreadsheets or HTML tables.
- Can I deduplicate lines from a very large text file?
- Yes. The Remove Duplicate Lines tool runs entirely in your browser using JavaScript, so performance depends on your device's memory and CPU. Files with tens of thousands of lines process instantly. Files with millions of lines (multi-megabyte text files) may take a few seconds and use significant browser memory. There is no hard size limit enforced by the tool. For very large files (hundreds of megabytes), a command-line approach using sort -u or awk '!seen[$0]++' is faster and less memory-intensive.
Local processing
Our local file, text and chart tools process content on your device using JavaScript, browser APIs and, where needed, WebAssembly. Our usage events do not include filenames, file contents, input text, chart values, raw errors, emails or license references. Network lookup tools (such as DNS, WHOIS, IP and speed tests) contact external services for their stated purpose. Loading the website, fonts, libraries and models also makes network requests. WebAssembly itself does not prevent network access.